 llmrun
Local LLMs on AWS GPU
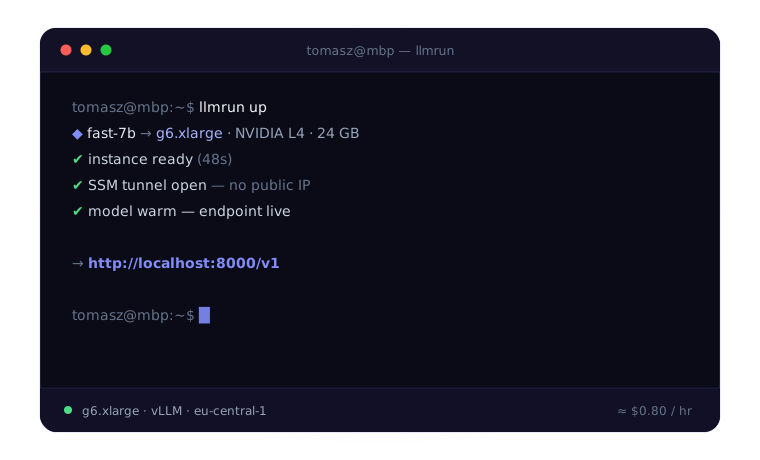
Work locally with deployed open-models in your cloud. No local GPU, no public IP, no per-token billing.
llmrun studio
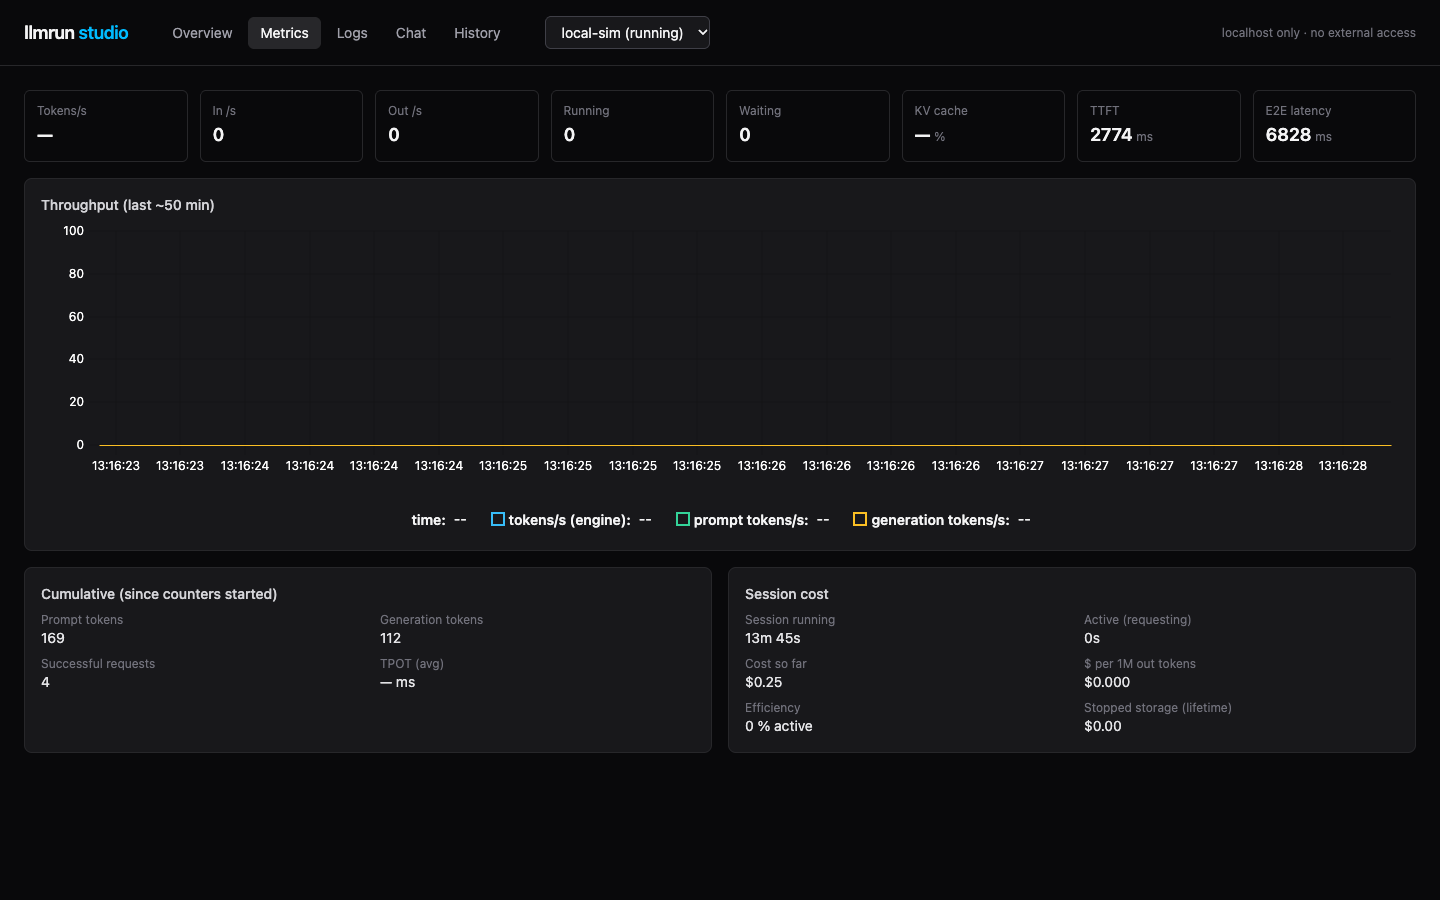
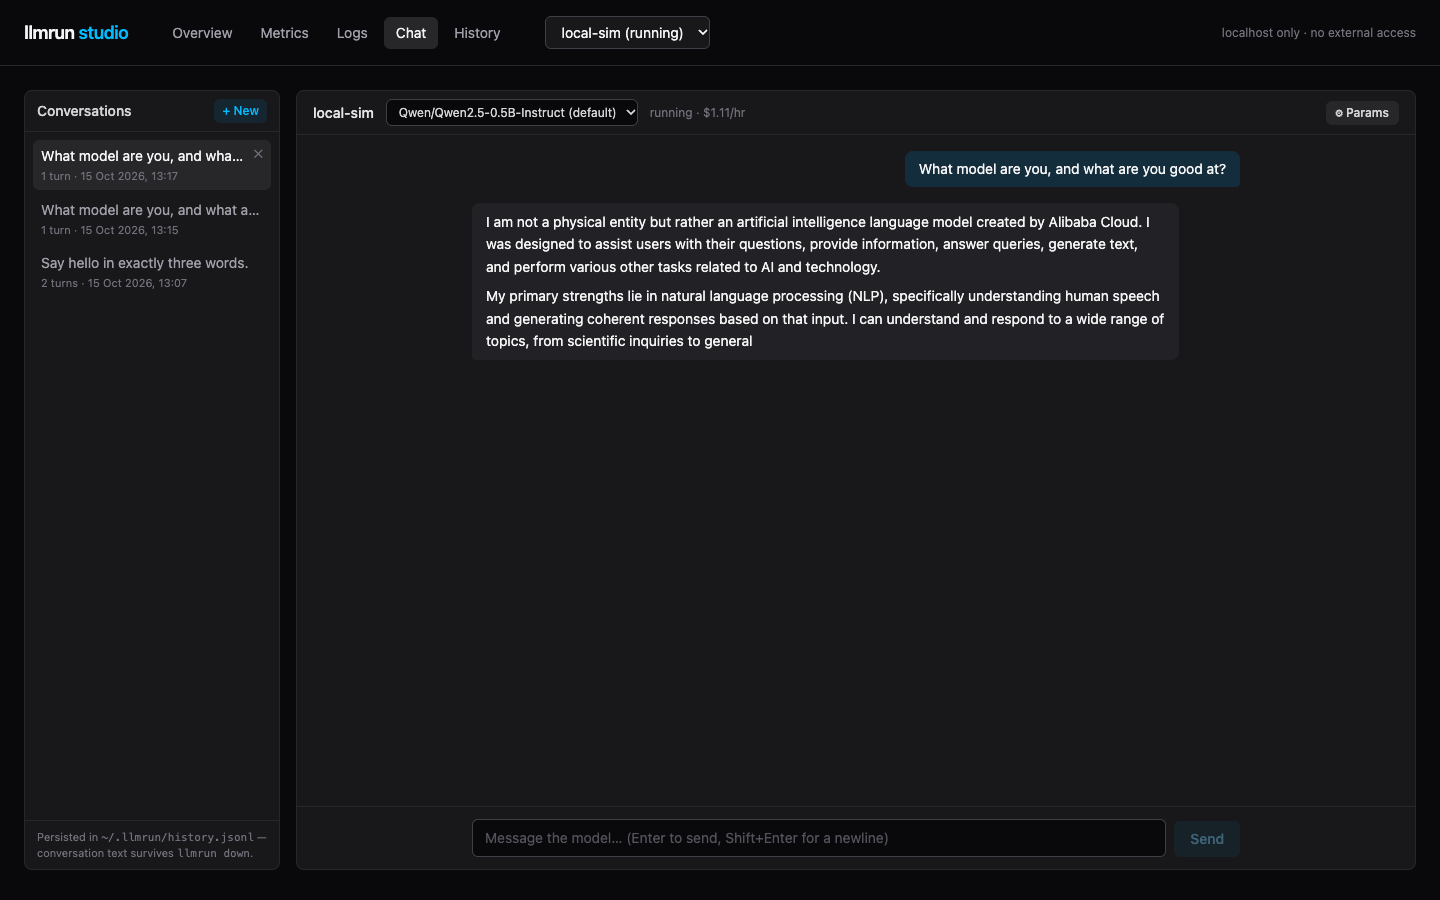
A local, Docker-Desktop-style dashboard for what you’re running: live metrics straight from vLLM, a ChatGPT-style chat against the served model, and cost history that survives llmrun down. Binds to 127.0.0.1 only.

No local GPU required
Your laptop stays cool. Models run on the right-sized AWS GPU instance — spin it up when you need it, let it stop itself when you don't.

Pay for infrastructure, not tokens
No per-token pricing. You pay AWS on-demand rates (~$0.80/hr) only while the instance is running. Idle auto-stop means you're rarely paying for nothing.

Your data stays in your cloud
Inference never leaves your AWS account. No third-party API receives your prompts, code, or documents — full isolation for sensitive or proprietary work.

Editable model catalog
llmrun.yaml maps a friendly alias to a HuggingFace repo and the GPU instance needed to serve it. Add, swap, or pin any open-source model in seconds.

No public IP, no SSH keys
Access is entirely over AWS SSM port-forwarding. No inbound security group rules, no bastion host, no key pair to manage.

Run multiple models at once
Each deployment gets its own local port (8000, 8001, …). Forward all concurrently — point different tools at different models without disconnecting anything.